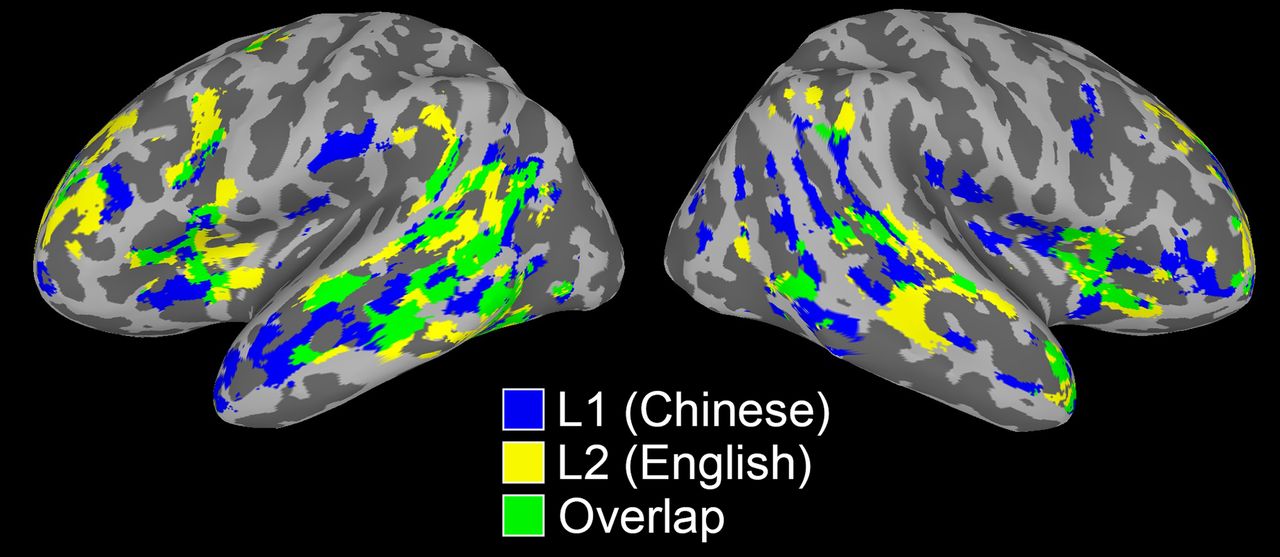
Figure 5.
Spatially interleaved distribution of informative voxels for identifying grammatical meanings in each language. The colored voxels were consistently (simulation-based p = 0.05) selected across participants for modeling grammatical features. The association of the voxels' distance with the weight similarity was negligible (Extended Data Fig. 5-1). Voxels representing Chinese (L1) sentences were more right-lateralized than those over English (L2) sentences (Extended Data Fig. 5-2). Voxels representing L2 grammatical features were more varied across participants (Extended Data Figs. 5-3, 5-4).


